


[Dec 19, 2021] Verified Professional-Machine-Learning-Engineer dumps and 72 unique questions
Professional-Machine-Learning-Engineer Dumps for Pass Guaranteed - Pass Professional-Machine-Learning-Engineer Exam 2021
Understanding functional and technical aspects of Professional Machine Learning Engineer - Google ML Model Development
The following will be discussed in Google Professional-Machine-Learning-Engineer dumps:
- Scalable model analysis (e.g. Cloud Storage output files, Dataflow, BigQuery, Google Data Studio)
- Model explainability on Cloud AI Platform
- Training a model as a job in different environments
- Modeling techniques given interpretability requirements
- Productionizing
- Model performance against baselines, simpler models, and across the time dimension
- Distributed training
- Overfitting
- Transfer learning
- Build a model
- Retraining/redeployment evaluation
- Tracking metrics during training
- Hardware accelerators
- Model generalization
- Unit tests for model training and serving
- Choice of framework and model
- Scale model training and serving
Understanding functional and technical aspects of Professional Machine Learning Engineer - Google ML Problem Framing
The following will be discussed in Google Professional-Machine-Learning-Engineer dumps:
- Identify risks to feasibility and implementation of ML solution. Considerations include:
- Defining outcome of model predictions
- Managing incorrect results
- Defining the input (features) and predicted output format
- Defining business problems
- Key results
- Identifying nonML solutions
- Aligning with Google AI principles and practices (e.g. different biases)
- Assessing ML solution readiness
- Define ML problem
- Defining output use
- Assessing data readiness
- Defining problem type (classification, regression, clustering, etc.)
- Success metrics
- Determination of when a model is deemed unsuccessful
- Identifying data sources
- Assessing and communicating business impact
- Define business success criteria
NEW QUESTION 17
You need to build classification workflows over several structured datasets currently stored in BigQuery. Because you will be performing the classification several times, you want to complete the following steps without writing code: exploratory data analysis, feature selection, model building, training, and hyperparameter tuning and serving. What should you do?
- A. Use Al Platform Notebooks to run the classification model with pandas library
- B. Run a BigQuery ML task to perform logistic regression for the classification
- C. Use Al Platform to run the classification model job configured for hyperparameter tuning
- D. Configure AutoML Tables to perform the classification task
Answer: A
NEW QUESTION 18
A large company has developed a BI application that generates reports and dashboards using data collected from various operational metrics. The company wants to provide executives with an enhanced experience so they can use natural language to get data from the reports. The company wants the executives to be able ask questions using written and spoken interfaces.
Which combination of services can be used to build this conversational interface? (Choose three.)
- A. Amazon Lex
- B. Amazon Transcribe
- C. Amazon Polly
- D. Amazon Connect
- E. Alexa for Business
- F. Amazon Comprehend
Answer: B,D,F
NEW QUESTION 19
During batch training of a neural network, you notice that there is an oscillation in the loss. How should you adjust your model to ensure that it converges?
- A. Decrease the size of the training batch
- B. Decrease the learning rate hyperparameter
- C. Increase the learning rate hyperparameter
- D. Increase the size of the training batch
Answer: C
NEW QUESTION 20
A Machine Learning Specialist is developing a daily ETL workflow containing multiple ETL jobs. The workflow consists of the following processes:
* Start the workflow as soon as data is uploaded to Amazon S3.
* When all the datasets are available in Amazon S3, start an ETL job to join the uploaded datasets with multiple terabyte-sized datasets already stored in Amazon S3.
* Store the results of joining datasets in Amazon S3.
* If one of the jobs fails, send a notification to the Administrator.
Which configuration will meet these requirements?
- A. Use AWS Lambda to trigger an AWS Step Functions workflow to wait for dataset uploads to complete in Amazon S3. Use AWS Glue to join the datasets. Use an Amazon CloudWatch alarm to send an SNS notification to the Administrator in the case of a failure.
- B. Develop the ETL workflow using AWS Lambda to start an Amazon SageMaker notebook instance. Use a lifecycle configuration script to join the datasets and persist the results in Amazon S3. Use an Amazon CloudWatch alarm to send an SNS notification to the Administrator in the case of a failure.
- C. Use AWS Lambda to chain other Lambda functions to read and join the datasets in Amazon S3 as soon as the data is uploaded to Amazon S3. Use an Amazon CloudWatch alarm to send an SNS notification to the Administrator in the case of a failure.
- D. Develop the ETL workflow using AWS Batch to trigger the start of ETL jobs when data is uploaded to Amazon S3. Use AWS Glue to join the datasets in Amazon S3. Use an Amazon CloudWatch alarm to send an SNS notification to the Administrator in the case of a failure.
Answer: A
Explanation:
Explanation/Reference: https://aws.amazon.com/step-functions/use-cases/
NEW QUESTION 21
A Machine Learning Specialist is working with a large cybersecurity company that manages security events in real time for companies around the world. The cybersecurity company wants to design a solution that will allow it to use machine learning to score malicious events as anomalies on the data as it is being ingested. The company also wants be able to save the results in its data lake for later processing and analysis.
What is the MOST efficient way to accomplish these tasks?
- A. Ingest the data and store it in Amazon S3. Use AWS Batch along with the AWS Deep Learning AMIs to train a k-means model using TensorFlow on the data in Amazon S3.
- B. Ingest the data using Amazon Kinesis Data Firehose, and use Amazon Kinesis Data Analytics Random Cut Forest (RCF) for anomaly detection. Then use Kinesis Data Firehose to stream the results to Amazon S3.
- C. Ingest the data and store it in Amazon S3. Have an AWS Glue job that is triggered on demand transform the new data. Then use the built-in Random Cut Forest (RCF) model within Amazon SageMaker to detect anomalies in the data.
- D. Ingest the data into Apache Spark Streaming using Amazon EMR, and use Spark MLlib with k-means to perform anomaly detection. Then store the results in an Apache Hadoop Distributed File System (HDFS) using Amazon EMR with a replication factor of three as the data lake.
Answer: D
NEW QUESTION 22
You have a demand forecasting pipeline in production that uses Dataflow to preprocess raw data prior to model training and prediction. During preprocessing, you employ Z-score normalization on data stored in BigQuery and write it back to BigQuery. New training data is added every week. You want to make the process more efficient by minimizing computation time and manual intervention. What should you do?
- A. Use the normalizer_fn argument in TensorFlow's Feature Column API
- B. Normalize the data using Google Kubernetes Engine
- C. Translate the normalization algorithm into SQL for use with BigQuery
- D. Normalize the data with Apache Spark using the Dataproc connector for BigQuery
Answer: C
NEW QUESTION 23
You have trained a deep neural network model on Google Cloud. The model has low loss on the training data, but is performing worse on the validation dat a. You want the model to be resilient to overfitting. Which strategy should you use when retraining the model?
- A. Run a hyperparameter tuning job on Al Platform to optimize for the L2 regularization and dropout parameters
- B. Run a hyperparameter tuning job on Al Platform to optimize for the learning rate, and increase the number of neurons by a factor of 2.
- C. Apply a dropout parameter of 0 2, and decrease the learning rate by a factor of 10
- D. Apply a 12 regularization parameter of 0.4, and decrease the learning rate by a factor of 10.
Answer: C
NEW QUESTION 24
You work with a data engineering team that has developed a pipeline to clean your dataset and save it in a Cloud Storage bucket. You have created an ML model and want to use the data to refresh your model as soon as new data is available. As part of your CI/CD workflow, you want to automatically run a Kubeflow Pipelines training job on Google Kubernetes Engine (GKE). How should you architect this workflow?
- A. Use Cloud Scheduler to schedule jobs at a regular interval. For the first step of the job. check the timestamp of objects in your Cloud Storage bucket If there are no new files since the last run, abort the job.
- B. Configure a Cloud Storage trigger to send a message to a Pub/Sub topic when a new file is available in a storage bucket. Use a Pub/Sub-triggered Cloud Function to start the training job on a GKE cluster
- C. Use App Engine to create a lightweight python client that continuously polls Cloud Storage for new files As soon as a file arrives, initiate the training job
- D. Configure your pipeline with Dataflow, which saves the files in Cloud Storage After the file is saved, start the training job on a GKE cluster
Answer: B
NEW QUESTION 25
A Machine Learning Specialist is given a structured dataset on the shopping habits of a company's customer base. The dataset contains thousands of columns of data and hundreds of numerical columns for each customer. The Specialist wants to identify whether there are natural groupings for these columns across all customers and visualize the results as quickly as possible.
What approach should the Specialist take to accomplish these tasks?
- A. Embed the numerical features using the t-distributed stochastic neighbor embedding (t-SNE) algorithm and create a line graph.
- B. Embed the numerical features using the t-distributed stochastic neighbor embedding (t-SNE) algorithm and create a scatter plot.
- C. Run k-means using the Euclidean distance measure for different values of k and create an elbow plot.
- D. Run k-means using the Euclidean distance measure for different values of k and create box plots for each numerical column within each cluster.
Answer: C
NEW QUESTION 26
You work with a data engineering team that has developed a pipeline to clean your dataset and save it in a Cloud Storage bucket. You have created an ML model and want to use the data to refresh your model as soon as new data is available. As part of your CI/CD workflow, you want to automatically run a Kubeflow Pipelines training job on Google Kubernetes Engine (GKE). How should you architect this workflow?
- A. Configure a Cloud Storage trigger to send a message to a Pub/Sub topic when a new file is available in a storage bucket. Use a Pub/Sub-triggered Cloud Function to start the training job on a GKE cluster
- B. Use Cloud Scheduler to schedule jobs at a regular interval. For the first step of the job. check the timestamp of objects in your Cloud Storage bucket If there are no new files since the last run, abort the job.
- C. Configure your pipeline with Dataflow, which saves the files in Cloud Storage After the file is saved, start the training job on a GKE cluster
- D. Use App Engine to create a lightweight python client that continuously polls Cloud Storage for new files As soon as a file arrives, initiate the training job
Answer: C
NEW QUESTION 27
You are designing an architecture with a serveress ML system to enrich customer support tickets with informative metadata before they are routed to a support agent. You need a set of models to predict ticket priority, predict ticket resolution time, and perform sentiment analysis to help agents make strategic decisions when they process support requests. Tickets are not expected to have any domain-specific terms or jargon.
The proposed architecture has the following flow: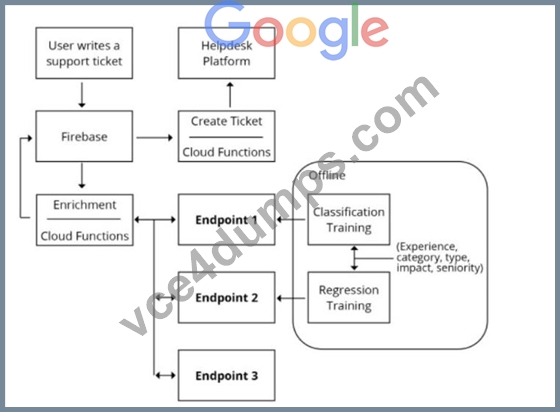
Which endpoints should the Enrichment Cloud Functions call?
- A. 1 = Al Platform, 2 = Al Platform, 3 = AutoML Natural Language
- B. 1 = Al Platform, 2 = Al Platform, 3 = Cloud Natural Language API
- C. 1 = cloud Natural Language API, 2 = Al Platform, 3 = Cloud Vision API
- D. 1 = Al Platform, 2 = Al Platform, 3 = AutoML Vision
Answer: A
NEW QUESTION 28
An interactive online dictionary wants to add a widget that displays words used in similar contexts. A Machine Learning Specialist is asked to provide word features for the downstream nearest neighbor model powering the widget.
What should the Specialist do to meet these requirements?
- A. Produce a set of synonyms for every word using Amazon Mechanical Turk.
- B. Create one-hot word encoding vectors.
- C. Download word embeddings pre-trained on a large corpus.
- D. Create word embedding vectors that store edit distance with every other word.
Answer: B
Explanation:
Explanation/Reference: https://aws.amazon.com/blogs/machine-learning/amazon-sagemaker-object2vec-adds-new- features-that-support-automatic-negative-sampling-and-speed-up-training/
NEW QUESTION 29
An employee found a video clip with audio on a company's social media feed. The language used in the video is Spanish. English is the employee's first language, and they do not understand Spanish. The employee wants to do a sentiment analysis.
What combination of services is the MOST efficient to accomplish the task?
- A. Amazon Transcribe, Amazon Translate, and Amazon Comprehend
- B. Amazon Transcribe, Amazon Translate, and Amazon SageMaker Neural Topic Model (NTM)
- C. Amazon Transcribe, Amazon Translate and Amazon SageMaker BlazingText
- D. Amazon Transcribe, Amazon Comprehend, and Amazon SageMaker seq2seq
Answer: B
NEW QUESTION 30
A company that promotes healthy sleep patterns by providing cloud-connected devices currently hosts a sleep tracking application on AWS. The application collects device usage information from device users. The company's Data Science team is building a machine learning model to predict if and when a user will stop utilizing the company's devices. Predictions from this model are used by a downstream application that determines the best approach for contacting users.
The Data Science team is building multiple versions of the machine learning model to evaluate each version against the company's business goals. To measure long-term effectiveness, the team wants to run multiple versions of the model in parallel for long periods of time, with the ability to control the portion of inferences served by the models.
Which solution satisfies these requirements with MINIMAL effort?
- A. Build and host multiple models in Amazon SageMaker. Create multiple Amazon SageMaker endpoints, one for each model. Programmatically control invoking different models for inference at the application layer.
- B. Build and host multiple models in Amazon SageMaker. Create a single endpoint that accesses multiple models. Use Amazon SageMaker batch transform to control invoking the different models through the single endpoint.
- C. Build and host multiple models in Amazon SageMaker Neo to take into account different types of medical devices. Programmatically control which model is invoked for inference based on the medical device type.
- D. Build and host multiple models in Amazon SageMaker. Create an Amazon SageMaker endpoint configuration with multiple production variants. Programmatically control the portion of the inferences served by the multiple models by updating the endpoint configuration.
Answer: B
NEW QUESTION 31
Your organization's call center has asked you to develop a model that analyzes customer sentiments in each call. The call center receives over one million calls daily, and data is stored in Cloud Storage. The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. You need to select components for data processing and for analytics. How should the data pipeline be designed?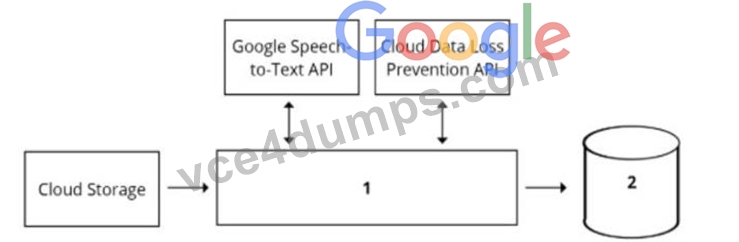
- A. 1 = Cloud Function, 2 = Cloud SQL
- B. 1 = Dataflow, 2 = BigQuery
- C. 1 = Pub/Sub, 2 = Datastore
- D. 1 = Dataflow, 2 = Cloud SQL
Answer: C
NEW QUESTION 32
You are building a model to predict daily temperatures. You split the data randomly and then transformed the training and test datasets. Temperature data for model training is uploaded hourly. During testing, your model performed with 97% accuracy; however, after deploying to production, the model's accuracy dropped to 66%. How can you make your production model more accurate?
- A. Normalize the data for the training, and test datasets as two separate steps.
- B. Split the training and test data based on time rather than a random split to avoid leakage
- C. Add more data to your test set to ensure that you have a fair distribution and sample for testing
- D. Apply data transformations before splitting, and cross-validate to make sure that the transformations are applied to both the training and test sets.
Answer: C
NEW QUESTION 33
You are an ML engineer at a global car manufacturer. You need to build an ML model to predict car sales in different cities around the world. Which features or feature crosses should you use to train city-specific relationships between car type and number of sales?
- A. Three individual features binned latitude, binned longitude, and one-hot encoded car type
- B. One feature obtained as an element-wise product between latitude, longitude, and car type
- C. Two feature crosses as a element-wise product the first between binned latitude and one-hot encoded car type, and the second between binned longitude and one-hot encoded car type
- D. One feature obtained as an element-wise product between binned latitude, binned longitude, and one-hot encoded car type
Answer: D
NEW QUESTION 34
A Machine Learning Specialist working for an online fashion company wants to build a data ingestion solution for the company's Amazon S3-based data lake.
The Specialist wants to create a set of ingestion mechanisms that will enable future capabilities comprised of:
* Real-time analytics
* Interactive analytics of historical data
* Clickstream analytics
* Product recommendations
Which services should the Specialist use?
- A. AWS Glue as the data catalog; Amazon Kinesis Data Streams and Amazon Kinesis Data Analytics for historical data insights; Amazon Kinesis Data Firehose for delivery to Amazon ES for clickstream analytics; Amazon EMR to generate personalized product recommendations
- B. Amazon Athena as the data catalog; Amazon Kinesis Data Streams and Amazon Kinesis Data Analytics for historical data insights; Amazon DynamoDB streams for clickstream analytics; AWS Glue to generate personalized product recommendations
- C. AWS Glue as the data catalog; Amazon Kinesis Data Streams and Amazon Kinesis Data Analytics for real- time data insights; Amazon Kinesis Data Firehose for delivery to Amazon ES for clickstream analytics; Amazon EMR to generate personalized product recommendations
- D. Amazon Athena as the data catalog: Amazon Kinesis Data Streams and Amazon Kinesis Data Analytics for near-real-time data insights; Amazon Kinesis Data Firehose for clickstream analytics; AWS Glue to generate personalized product recommendations
Answer: C
Explanation:
Explanation
NEW QUESTION 35
A Data Scientist is working on an application that performs sentiment analysis. The validation accuracy is poor, and the Data Scientist thinks that the cause may be a rich vocabulary and a low average frequency of words in the dataset.
Which tool should be used to improve the validation accuracy?
- A. Scikit-leam term frequency-inverse document frequency (TF-IDF) vectorizer
- B. Amazon Comprehend syntax analysis and entity detection
- C. Natural Language Toolkit (NLTK) stemming and stop word removal
- D. Amazon SageMaker BlazingText cbowmode
Answer: A
Explanation:
Explanation/Reference: https://monkeylearn.com/sentiment-analysis/
NEW QUESTION 36
A technology startup is using complex deep neural networks and GPU compute to recommend the company's products to its existing customers based upon each customer's habits and interactions. The solution currently pulls each dataset from an Amazon S3 bucket before loading the data into a TensorFlow model pulled from the company's Git repository that runs locally. This job then runs for several hours while continually outputting its progress to the same S3 bucket. The job can be paused, restarted, and continued at any time in the event of a failure, and is run from a central queue.
Senior managers are concerned about the complexity of the solution's resource management and the costs involved in repeating the process regularly. They ask for the workload to be automated so it runs once a week, starting Monday and completing by the close of business Friday.
Which architecture should be used to scale the solution at the lowest cost?
- A. Implement the solution using Amazon ECS running on Spot Instances and schedule the task using the ECS service scheduler
- B. Implement the solution using AWS Deep Learning Containers and run the container as a job using AWS Batch on a GPU-compatible Spot Instance
- C. Implement the solution using a low-cost GPU-compatible Amazon EC2 instance and use the AWS Instance Scheduler to schedule the task
- D. Implement the solution using AWS Deep Learning Containers, run the workload using AWS Fargate running on Spot Instances, and then schedule the task using the built-in task scheduler
Answer: D
NEW QUESTION 37
Your organization's call center has asked you to develop a model that analyzes customer sentiments in each call. The call center receives over one million calls daily, and data is stored in Cloud Storage. The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (Pll) can be stored or analyzed. The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. You need to select components for data processing and for analytics. How should the data pipeline be designed?
- A. 1 = Pub/Sub, 2 = Datastore
- B. 1 = Dataflow, 2 = BigQuery
- C. 1 = Dataflow, 2 = Cloud SQL
- D. 1 = Cloud Function, 2 = Cloud SQL
Answer: D
NEW QUESTION 38
......
Professional Machine Learning Engineer - Google Certification Path
The associate level certification is focused on the fundamental skills of deploying, monitoring, and maintaining projects on Google Cloud. This certification is a good starting point for those new to cloud and can be used as a path to professional level certifications.
Professional certifications span key technical job functions and assess advanced skills in design, implementation, and management. These certifications are recommended for individuals with industry experience and familiarity with Google Cloud products and solutions.
Latest 100% Passing Guarantee - Brilliant Professional-Machine-Learning-Engineer Exam Questions PDF: https://www.vce4dumps.com/Professional-Machine-Learning-Engineer-valid-torrent.html
Professional-Machine-Learning-Engineer Exam Dumps - Try Best Professional-Machine-Learning-Engineer Exam Questions: https://drive.google.com/open?id=1qU5SWVSUGUthMEEFTXZsa1xmIFWUQEz4